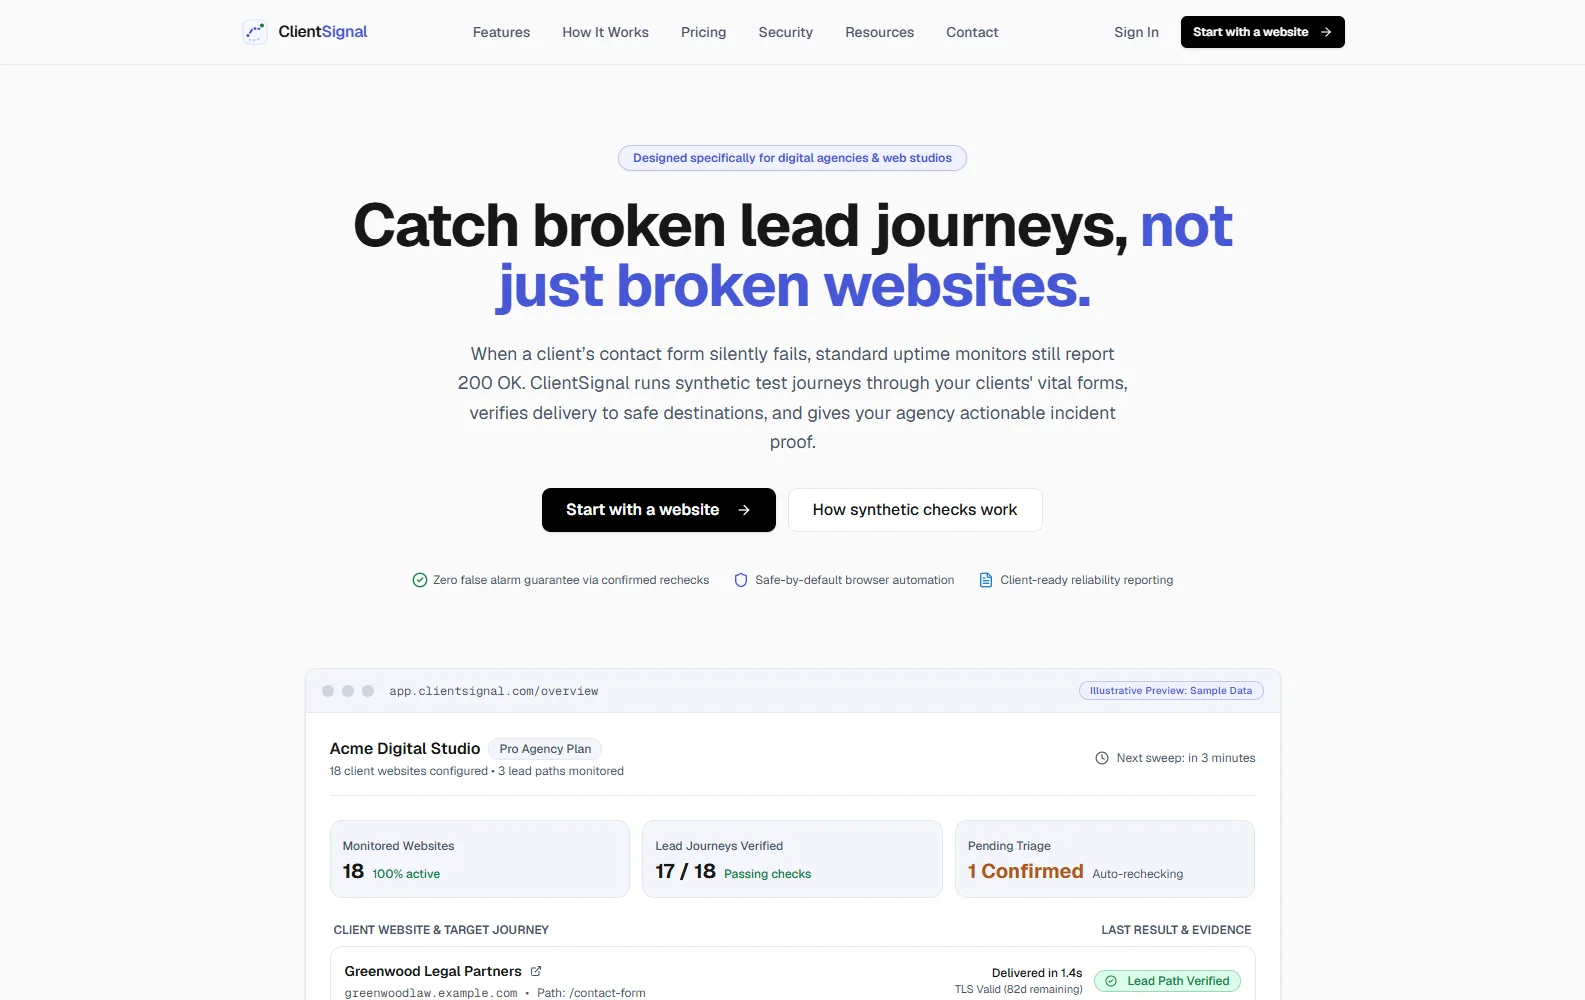
Unified Operational Signal Overview
Consolidates endpoint health, regional cluster latency, and active alerts into a single high-density workspace.
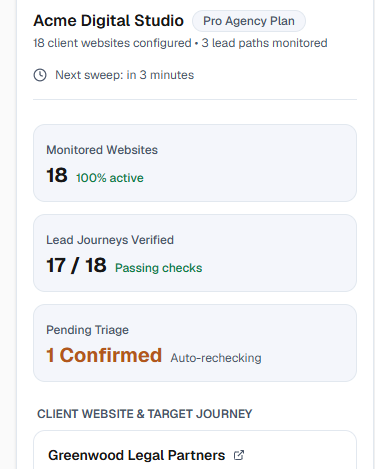
Mobile On-Call Triage
Responsive incident status and alert acknowledgement built for SREs on the move.
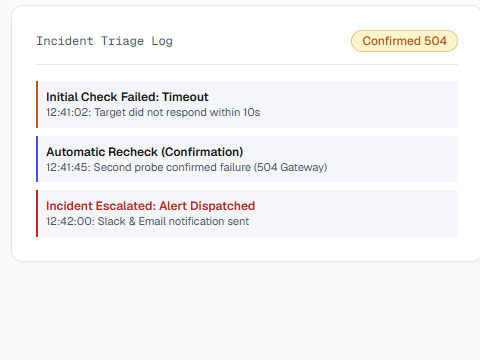
Incident Triage & Timelines
Pinpoints degraded microservices and tracks resolution steps across engineering teams.
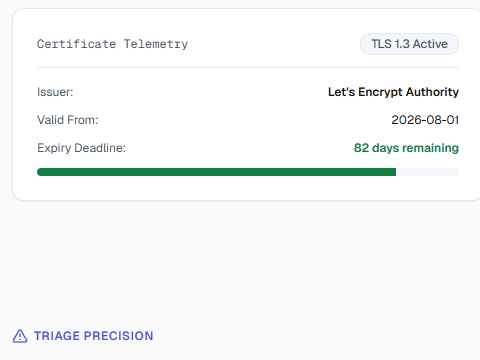
Certificate & Probe Telemetry
Automated SSL/TLS expiration tracking paired with synthetic lead-journey probes.
Multi-Tenant RBAC Controls
Role-isolated permissions separating cluster mutation, read-only auditing, and billing.
Product architecture and deliverables
How we structured the product, interface system, and engineering workflow.
Sub-Second Anomaly & Incident Boards
Surfaces degraded clusters, certificate expirations, and latency spikes in a high-density operational console.
- Real-time regional node health and latency tracking
- Automated incident triage and severity routing
- Zero-clutter dark and light telemetry views
Role-Based Access & Tenant Isolation
Enforces strict permission boundaries across Super Admins, SRE operators, read-only auditors, and billing leads.
- Granular cluster mutate and node-drain permissions
- Tenant-scoped session verification and audit logs
- Dedicated commercial and security control surfaces
Synthetic Lead & Endpoint Probing
Continuously verifies critical customer journeys, TLS certificates, and API uptime across global edge locations.
- Multi-step synthetic user journey verification
- Automated SSL/TLS certificate expiry telemetry
- Scheduled maintenance reporting for stakeholders
Resilient Time-Series & Event Schema
Structured around high-throughput event ingestion and deterministic alerting so teams never miss a production regression.
- Normalized incident, probe, and tenant schemas
- Fast filtering across services, regions, and status
- Responsive mobile on-call status views
More shipped work
All workUziri
Cinematic digital platform for Nairobi visual storytelling collective Uziri, uniting high-resolution film playback, GSAP gallery choreography, and print commerce.
Next →Project LUMA
Real-time WebGL2 fragment shader engine for procedural video synthesis, uniform-driven motion timelines, and deterministic frame export.
Start a project
Get started on your next product, website, or launch with our team.